
Professional AI Data Annotation Services & Managed Labeling
Need high-quality training data for your AI models? GetHumanCall provides managed, secure, and domain-specific AI annotation teams so your machine learning models are trained on accurate, real-world data from day one, no matter the modality, volume, or industry.
From computer vision to complex NLP, we combine human-in-the-loop expertise with strict quality control to help you deploy safe, reliable, and unbiased AI systems. Whether you're building your first proof-of-concept dataset or scaling a production pipeline that processes millions of data points a month, our teams plug directly into your existing workflow.
Why Managed Annotation Teams Outperform Crowdsourcing
Model performance is only as good as the ground truth it's trained on. Many AI teams struggle with inconsistent labeling, unverifiable annotator backgrounds, and data leaks when relying on open crowdsourcing platforms. These problems usually surface late, often after a model has already been trained on flawed data.
GetHumanCall removes those risks with fully managed, dedicated annotation operations: vetted specialists, standardized QA processes, and a single point of accountability for every dataset we touch. Unlike open crowdsourcing platforms, our annotators work under strict NDAs, follow GDPR-compliant protocols, and are matched to your specific industry rather than assigned at random. Every project is backed by multi-stage quality assurance, a dedicated project manager, and transparent SLAs, so accuracy holds steady even as volume scales up.
Our Core AI Data Annotation Capabilities
We support the full range of data types used to train modern AI and machine learning systems, across every stage of the model development lifecycle.
1. Image & Video Annotation (Computer Vision)
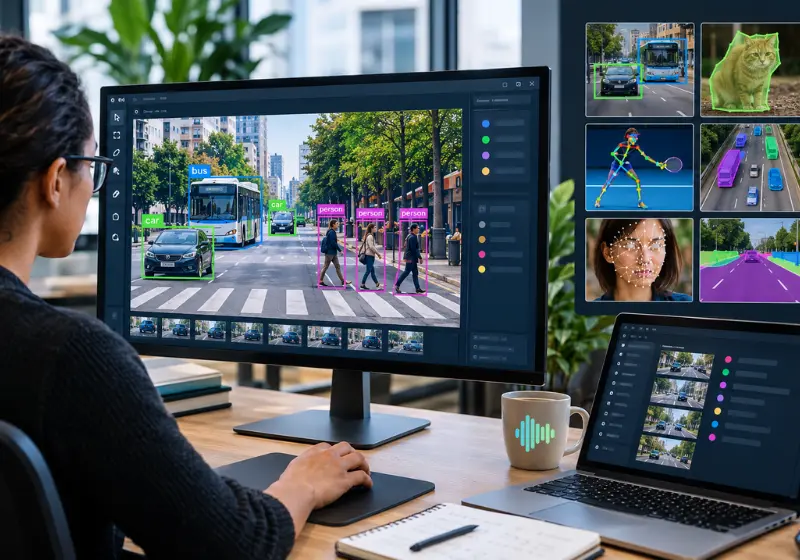
- Bounding Boxes & Polygons: High-volume object detection for e-commerce catalogues, retail shelf analytics, and security and surveillance systems.
- Semantic & Instance Segmentation: Pixel-level precision for medical imaging, precision agriculture, and autonomous driving perception stacks.
- Landmark & Keypoint Mapping: Detailed point tracking for pose estimation, facial recognition, and human motion analysis.
2. Text & NLP Data Labeling
- Named Entity Recognition (NER): Extracting key data points from legal contracts, financial reports, and medical records with domain-aware annotators.
- Sentiment & Emotion Analysis: Fine-tuning NLU models to recognize customer intent, frustration, sarcasm, and nuanced tone.
- Intent Classification: Structuring training datasets for advanced customer support chatbots and AI voice agents.
3. Audio & Speech Data Labeling
- Speech-to-Text Transcription: Multi-accent, multi-language transcription with custom domain-specific dictionaries and glossaries.
- Audio Sentiment & Prosody Tagging: Capturing tone, pitch, and pacing to train natural-sounding, emotionally aware conversational AI.
4. LiDAR & 3D Sensor Annotation
- 3D Bounding Cuboids: Precise labeling of point cloud data for robotics, spatial computing, and autonomous navigation systems.
How Our Annotation Process Works
Every engagement follows a structured, four-stage process designed to catch quality issues before they reach your model, not after.
- Scoping & Pilot: We review your labeling guidelines, edge cases, and existing taxonomy, then run a small pilot batch so you can validate accuracy before committing to full volume.
- Team Training & Calibration: Annotators are trained on your specific guidelines and tooling, with inter-annotator agreement measured until the team reaches consensus.
- Production & Continuous QA: Labeling runs at your required throughput, with multi-stage review, spot-checks, and real-time accuracy dashboards.
- Delivery & Iterative Feedback: Labeled data is delivered in your preferred format via API or direct export, with a feedback loop to refine edge-case handling as your model evolves.
Industries We Serve
Our annotation teams are matched to your sector, not assigned generically, which is what makes domain-specific accuracy possible at scale.
- Autonomous Vehicles & Robotics: LiDAR, radar, and multi-sensor fusion labeling for perception and navigation systems.
- Healthcare & Medical Imaging: HIPAA-aware workflows for radiology, pathology, and diagnostic imaging datasets.
- Retail & E-commerce: Product recognition, visual search, and catalogue tagging at high volume.
- Financial Services & Insurance: Document classification, fraud-pattern labeling, and structured data extraction from unstructured records.
- Customer Experience & Conversational AI: Intent, sentiment, and transcription data to train chatbots, voice agents, and support automation.
Supported Annotation Tools & Tech Stack
Our annotators integrate seamlessly into your existing ML pipeline and platform of choice, so there's no need to migrate tooling or retrain internal teams:
- Computer Vision: CVAT, Kili Technology, Labelbox
- Multi-modal & NLP: Label Studio, Prodigy
- Custom Interfaces: Direct integration via API or your proprietary internal tools
Data Security & Quality Assurance Framework
Building reliable AI models requires complete confidence in how your data is handled, stored, and validated at every step:
- GDPR & Privacy Compliance: Anonymization protocols, secure access controls, and strict data isolation between client projects.
- Multi-Stage Validation: Inter-annotator agreement scoring, consensus modeling, and manual reviewer sign-off before delivery.
- Agile Pricing Models: Flexible engagement structures, including per-hour, per-label, or fixed per-project pricing to match your budget and volume.
Frequently Asked Questions
What is AI data annotation, and why does it matter?
AI data annotation is the process of labeling raw data, such as images, text, audio, or 3D point clouds, so machine learning models can learn to recognize patterns. Accurate annotation directly determines model performance, safety, and fairness.
What's the difference between managed annotation teams and crowdsourced labeling?
Managed teams use vetted, trained specialists working under NDAs with multi-stage QA, while crowdsourcing relies on anonymous, unverified workers with no consistency guarantees. Managed teams trade lower per-label cost for higher, more predictable accuracy.
How is data security handled during annotation projects?
All annotators work under strict NDAs and GDPR-compliant protocols, with anonymization, controlled access, and full data isolation between client projects, so sensitive datasets never mix or leak.
Which annotation tools does GetHumanCall support?
We work directly within CVAT, Kili Technology, Labelbox, Label Studio, and Prodigy, as well as custom or proprietary annotation interfaces connected via API.
How much do AI data annotation services cost?
Pricing depends on data type, volume, and required accuracy, with per-hour, per-label, and fixed per-project models available. Request a custom quote for pricing specific to your dataset.
How quickly can an annotation team scale up?
After an initial pilot batch and calibration phase, teams can scale to full production volume within days, with accuracy monitored continuously so quality doesn't drop as throughput increases.
Ready to Scale Your AI Training Data?
Stop spending engineering hours managing labeling pipelines. Get in touch with GetHumanCall today to discuss your dataset requirements and receive a tailored quote for your project.